Education
AI-Driven Literature Tagging and Research Platform
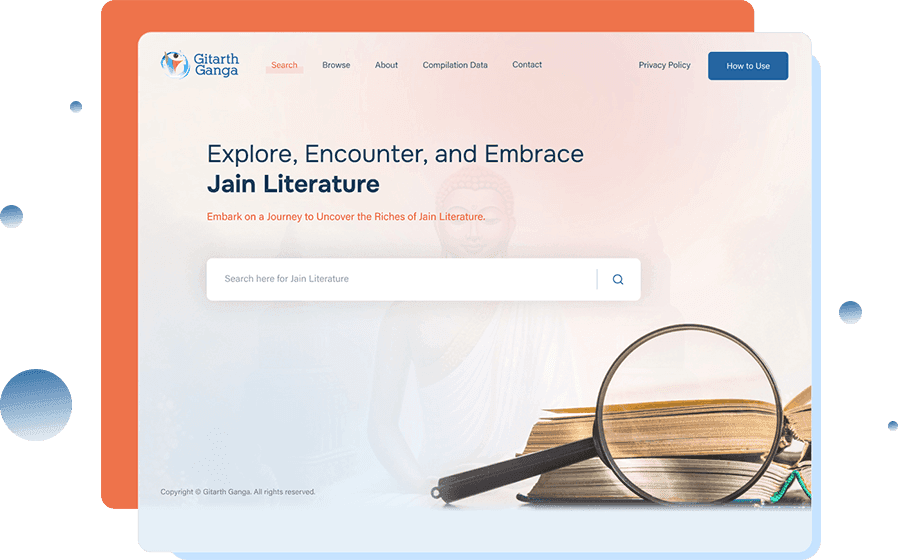
AI-powered academic research platform helping researchers, publishers, and enterprises to search, compile, and reuse knowledge from millions of scanned pages.
Overview
Aspire SoftServ worked with the client to create an AI-powered literature tagging and research platform using Intelligent Document Processing (IDP). The solution streamlines academic discovery by allowing users to extract, search, compile, and export research from millions of scanned pages automating what was once a fully manual process.
The client faced challenges like the absence of a centralized research platform, inefficient manual tagging, limited multi-user collaboration, dependency on physical processes, reduced operational efficiency due to lack of automation, and difficulty maintaining compliance and quality checks without robust admin controls.
TechStack


65%
Faster access to relevant content via AI-powered search

40%
Reduction in redundant searches with saved queries

90%+
OCR accuracy across 1.4M+ processed pages
Challenges
Addressing critical obstacles in academic research with AI-driven solutions.
The EdTech domain lacked a unified platform dedicated to book-based research, making it hard for researchers to access and organize academic resources in one place
Tagging and searching scanned documents required manual effort, consuming significant time and slowing down the overall research process without automated workflows.
Collaboration between researchers was limited due to poor traceability of work, making it challenging to coordinate tasks and share progress effectively.
Research workflows relied heavily on physical/manual processes rather than adopting modern EdTech tools, causing delays and reduced efficiency.
Without automation, the ability to reuse data was minimal, and operational efficiency suffered due to repetitive and redundant processes.
Managing compliance, quality checks, and reviewer activities was difficult without strong administrative tools and secure workflow controls.
Solution
Aspire built a secure, role-based web platform with OCR and NLP for smart tagging, search, and research compilation. It handles large volumes of scanned content, enables multi-user collaboration, and ensures controlled access via RBAC.

AI-Powered Tagging & Search
Identifies and extracts key terms from documents using frequency and relevance, ensuring precise tagging. Highlights the most relevant pages for each tag to speed up research discovery.

Query Management
Stores and organizes search history directly within user accounts, allowing quick retrieval of past queries. Helps researchers avoid repetitive searches and maintain a consistent research flow.

Smart Compilation Tool
Supports snippet extraction, detailed annotation, and structured organization of research content. Compiled results can be exported into clean, well-formatted PDFs for further use.

Role-Based Access Control (RBAC)
Implements distinct workflows for researchers, reviewers, and admins, ensuring the right access for each role. Maintains security and compliance through precise permission settings.

Secure Admin Operations
Includes audit trails for activity tracking, soft-delete for recovery, and super-admin oversight. Manages book ingestion with strict controls to maintain platform quality and security.

Scalable Processing Pipeline
Processes large volumes of PDFs and images without delays, ensuring efficiency at scale. Tracks each file’s status processed, failed, or pending for complete workflow transparency.
Business Impact
Create custom software tailored for your unique needs, including front-end, and core back-end technology.

Faster Access to Content
Achieved a 65% improvement in accessing relevant literature by using smart search features. Tag-based navigation further reduced the time spent finding key information.

Improved Collaboration
Over 100 research topics were compiled by more than 60 active users in six months. Multi-user access improved teamwork and streamlined project workflows.

Accurate AI Tagging
Processed over 2 million generated tags with strong contextual accuracy. The intelligent tagging system ensured consistent and precise classification of data.

Reduced Redundant Searches
Redundant searches dropped by 40% as saved queries were reused by 60% of users. This allowed researchers to quickly revisit prior findings without repeating work.

High-Volume Processing
Handled 1.4 million scanned pages with over 90% OCR accuracy. This ensured reliable data extraction even from large volumes of documents.

Enhanced Research Efficiency
Research workflows became faster and more organized for both researchers and reviewers. Clear role assignments and streamlined tools improved productivity across teams.
Want to accelerate software development at your company ? See how we can help.
We build custom software tailored to your unique needs—covering everything from front-end interfaces to core back-end systems.